Pricing is rarely the primary reason an organization picks a cloud provider, but it is always the reason they reconsider one.
 Editorial team
AWS Console in Brazil: What Engineers Need to Know
Brazilian cloud engineers interact with the AWS Management Console daily, but the experience differs meaningfully from what counterparts in us-east-1 or eu
AWS Brazil Office: What Cloud Engineers Need to Know in 2026
Since AWS launched its first South America Region in São Paulo (sa-east-1), Brazil has evolved from an emerging market footnote into a strategic hub for cl
Azure for Enterprises: Architecture, AKS, and Multi-Cloud Strategy
Enterprise adoption of Microsoft Azure has shifted from experimental workloads to full-scale platform commitments.
GCP vs Firebase: What Cloud Engineers Need to Know
Google Cloud Platform and Firebase are not competing products in the traditional sense — Firebase runs on top of GCP.
AI SRE Agents Resolve 11.4% of Real Incidents. Vendors
In IBM Research’s ITBench benchmark, agents built on state-of-the-art models resolved just 11.4% of realistic Site Reliability Engineering scenarios — Kubernetes environments with injected faults, full observability data, and a ReAct-style agent wired to logs, traces, metrics, and a shell. That same class of agent landed 25.2% on security operations …
 Editorial team
Anthropic Releases Claude 4 with 1M Context Window
Anthropic Releases Claude 4 with 1M Context Window Digesting Entire Monorepos: The Developer Workflow Revolution The 1M token context window represents a paradigm shift in how AI interacts with production codebases. One million tokens accommodates approximately 25,000-30,000 lines of code—enough to encompass a mid-sized microservice, a substantial internal library, or …
Why Trust, Not Raw Capability, Is Becoming the Real AI
The most interesting AI product debate happening right now is not about model benchmarks. It is about proof. A recent Reddit thread on r/artificial made the point in blunt terms: AI tools that cannot show what they did, which tools they used, what data they touched, and where humans approved …
The Trust Gap: Why AI Writes 80% of Code But Ships 0%
The 80/20 Problem Nobody Talks About Spend five minutes in any developer community and you’ll hear the same story: AI writes 80% of the code in minutes, and the remaining 20% eats the entire project timeline. GitHub and Google both report that 25–30% of their internal code is now AI-generated. …
Prompt Injection Is the Operational Risk Self-Hosted LLM
Prompt Injection Is the Operational Risk Self-Hosted LLM Teams Underestimate Self-hosting language models is often framed as a security upgrade. It can be one, but mostly for data residency, cost control, and model customization. It does not remove the core application risk that appears when a model can read untrusted …
Open-Weight Models vs SOTA in 2026: “Close Enough” Is a Strategy, Not a Ranking
Meta description: Open-weight models are now “good enough” for many real workloads—but the last 10% still matters. Here’s how to think about the gap to SOTA without worshiping benchmarks. Open-Weight Models vs SOTA in 2026: “Close Enough” Is a Strategy, Not a Ranking A weird thing happens when you spend …
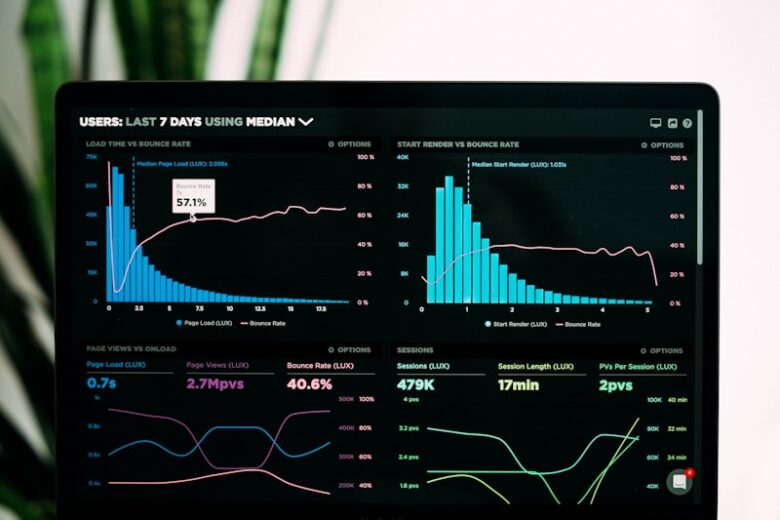
API Gateway Security: Rate Limiting and Authentication
Security is critical for production deployments. This guide covers comprehensive security practices including authentication, encryption, access control, and monitoring to protect your infrastructure from modern threats. Implementing proper security controls requires understanding the attack surface and applying defense in depth. Each component of your infrastructure needs specific security configurations tailored …